
Crawler
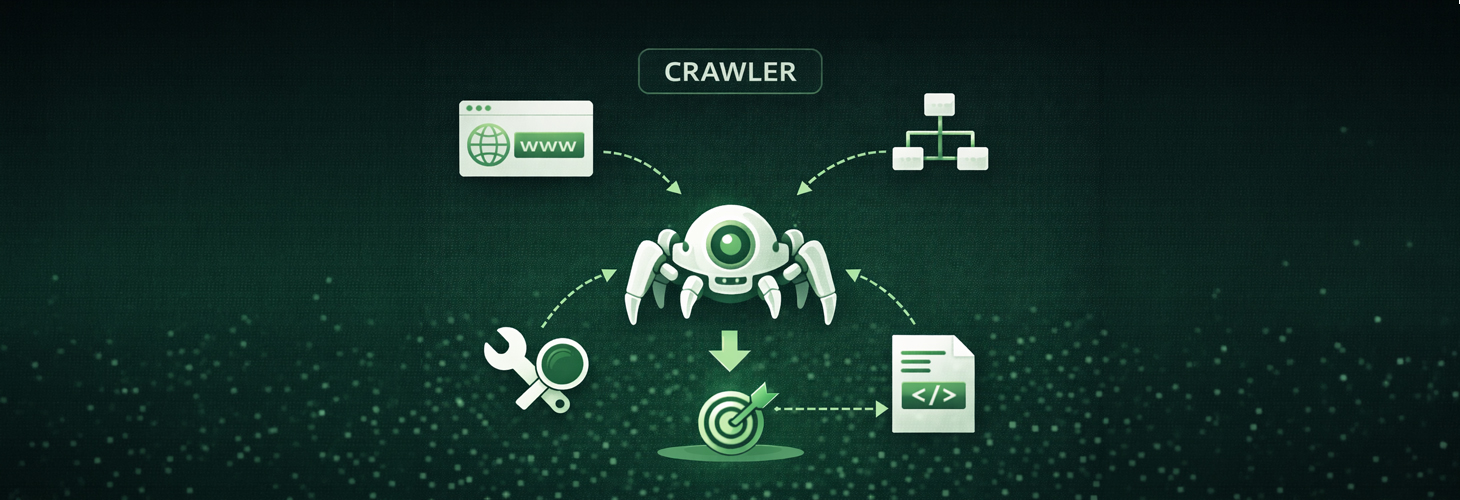
To capture the huge amount of content on the World Wide Web, search engines use crawlers – also called bots or spiders. Google's crawler is called Googlebot. It automatically visits web pages, reads their content and passes it on for inclusion in the index so that it can appear in the search results. It also picks up updates and changes. But crawlers aren't only used by search engines: SEO tools, price comparison portals and AI providers such as OpenAI also run their own crawlers – and unfortunately so do spammers, for example to harvest email addresses.
How does a crawler work? How does it read a page?
The first web crawler, the World Wide Web Wanderer, set off on its “wanderings” in 1993. The principle is still the same today: the crawler works its way through the web from link to link and discovers new pages that way. Google also uses XML sitemaps to find URLs. A crawler can't capture areas that can only be reached with a login. How often and how many pages of a website are crawled depends, among other things, on its importance, how frequently it is updated and server performance – this is known as crawl budget. Modern crawlers such as Googlebot can also execute JavaScript and render pages much like a browser.
After crawling, the search engine analyses the content, assigns it to topics and search terms and adds it to the index. Not every crawled page is indexed: Google decides for itself whether a page is relevant and unique enough. Google Search Console shows which pages have been crawled and indexed – and which haven't.
Googlebot & co.: crawlers in search engine optimisation
For search engine optimisation, the crawler is central, because only what it reaches can be found in search engines like Google. Since search engines are the most important traffic source for many websites and online shops, this is of great importance. Googlebot is the best-known example.
For the crawler to capture a website completely, it has to be accessible: important areas must not be blocked via robots.txt, and content should be delivered in the HTML or rendered reliably. Good internal linking is just as important, because the bot follows links. It may not find pages that are poorly linked or not linked at all. External backlinks also ensure that a website is visited more often. In large online shops with filters and variants in particular, it pays to direct the crawl budget specifically to the important pages. Whether important areas are blocked by mistake is checked by the robots.txt Checker.
Excluding areas deliberately: robots.txt, noindex and nofollow
Even if the goal is to be found as easily as possible, some areas shouldn't appear in the search results – such as login pages, internal search results or filter combinations without value of their own. There are different tools for this: robots.txt controls which areas crawlers shouldn't visit at all. With the “noindex” meta tag, a page remains accessible to the crawler but isn't added to the index. The “nofollow” link attribute, on the other hand, is only a hint not to follow a particular link – it is not enough to keep a page out of the index.